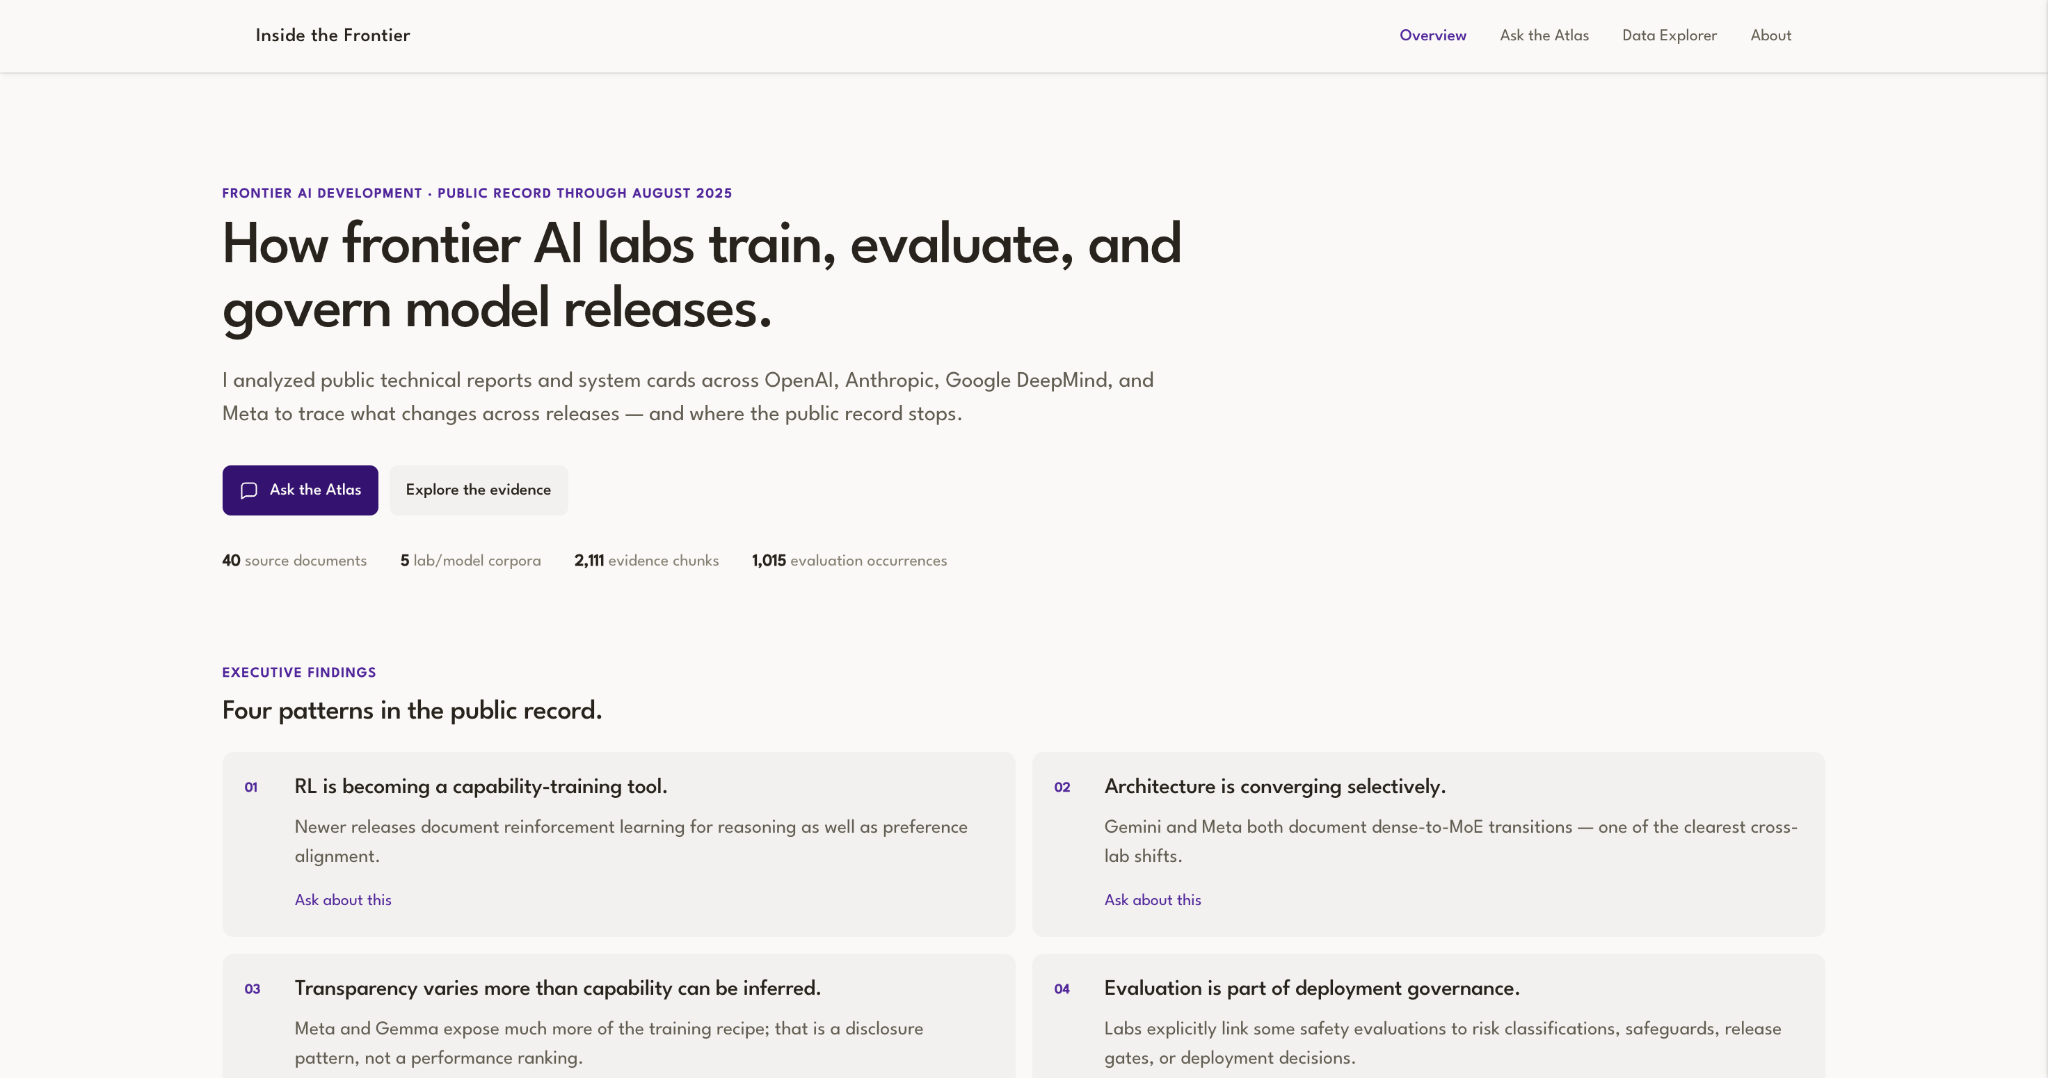
The Atlas opens with the findings, then lets readers inspect the evidence behind them.
Role
AI Research Intern · Product builder
Research synthesis · system design · implementation
Focus
AI evaluation + governance
Cross-lab comparability · grounded research
Skills
AI strategy · RAG / retrieval
Evaluation · safety & governance · data synthesis
Tools
Python · BM25 + BGE · FastAPI
Structured extraction · evidence audit · OpenAI API
00 / Question
Make frontier AI evidence comparable without pretending it is uniform.
I reviewed public technical reports and system cards from leading AI labs, then structured the evidence so readers could compare releases without losing the surrounding context.
40
reviewed source documents
2,111
indexed evidence chunks
1,015
evaluation occurrences
Research question
How do leading AI labs measure capability and risk, and how does that evidence connect to release decisions?
01 / Finding
The same benchmark was often not the same test.
Prompts, tools, attempt budgets, graders and thresholds varied across labs. A shared benchmark name was only the start of the comparison—not proof that two scores belonged in a ranking.
Strategy implication
Benchmark rankings can look more precise than the underlying public evidence allows.
Protocol audit: A shared benchmark name is a starting point. The surrounding protocol determines whether scores are truly comparable.
02 / Atlas
Move from finding to source without leaving the product.
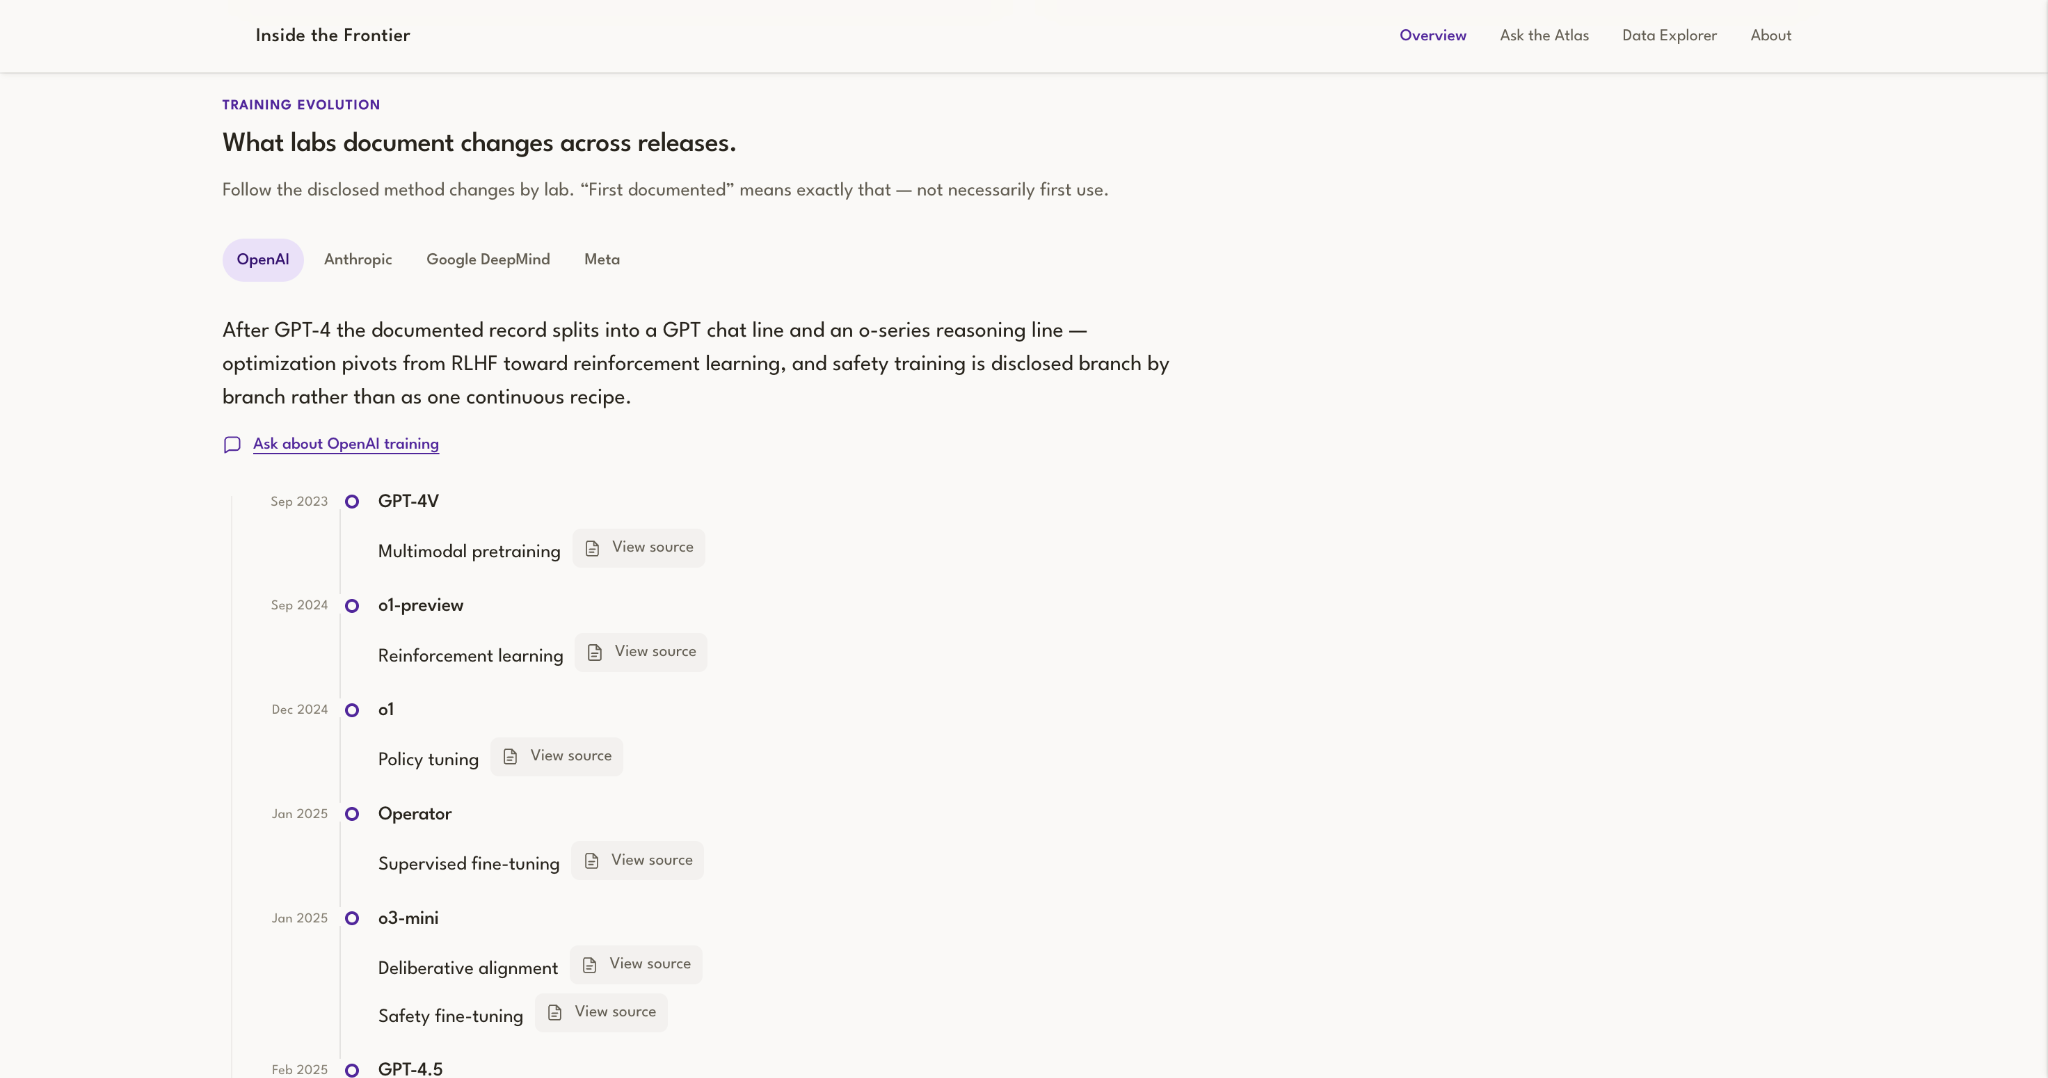
The Atlas combines concise findings, grounded question answering and a searchable evaluation catalog. Readers can open the source behind a claim instead of taking the synthesis on trust.
Selected screens
Inside the Atlas
3 views
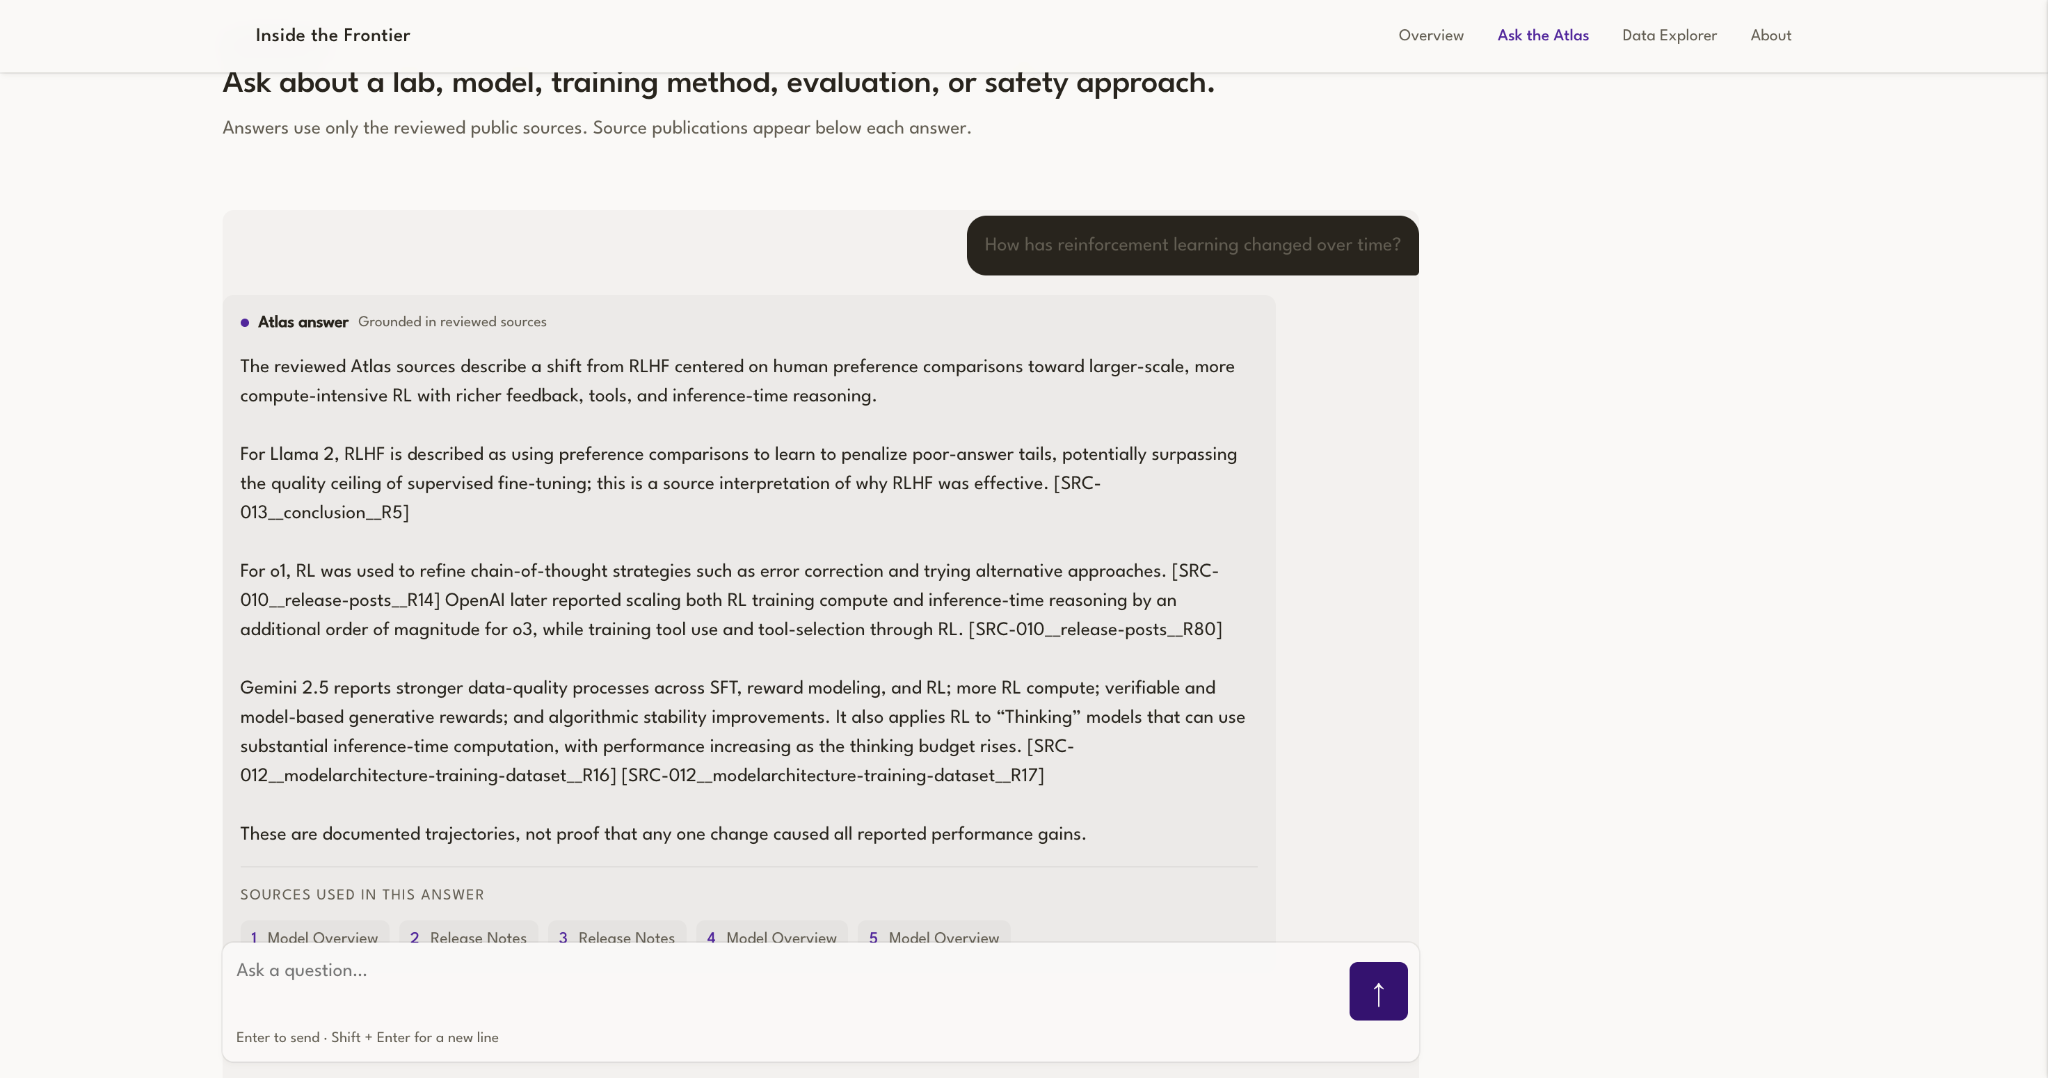
Ask the Atlas
A research question returns an answer grounded in the reviewed source library.
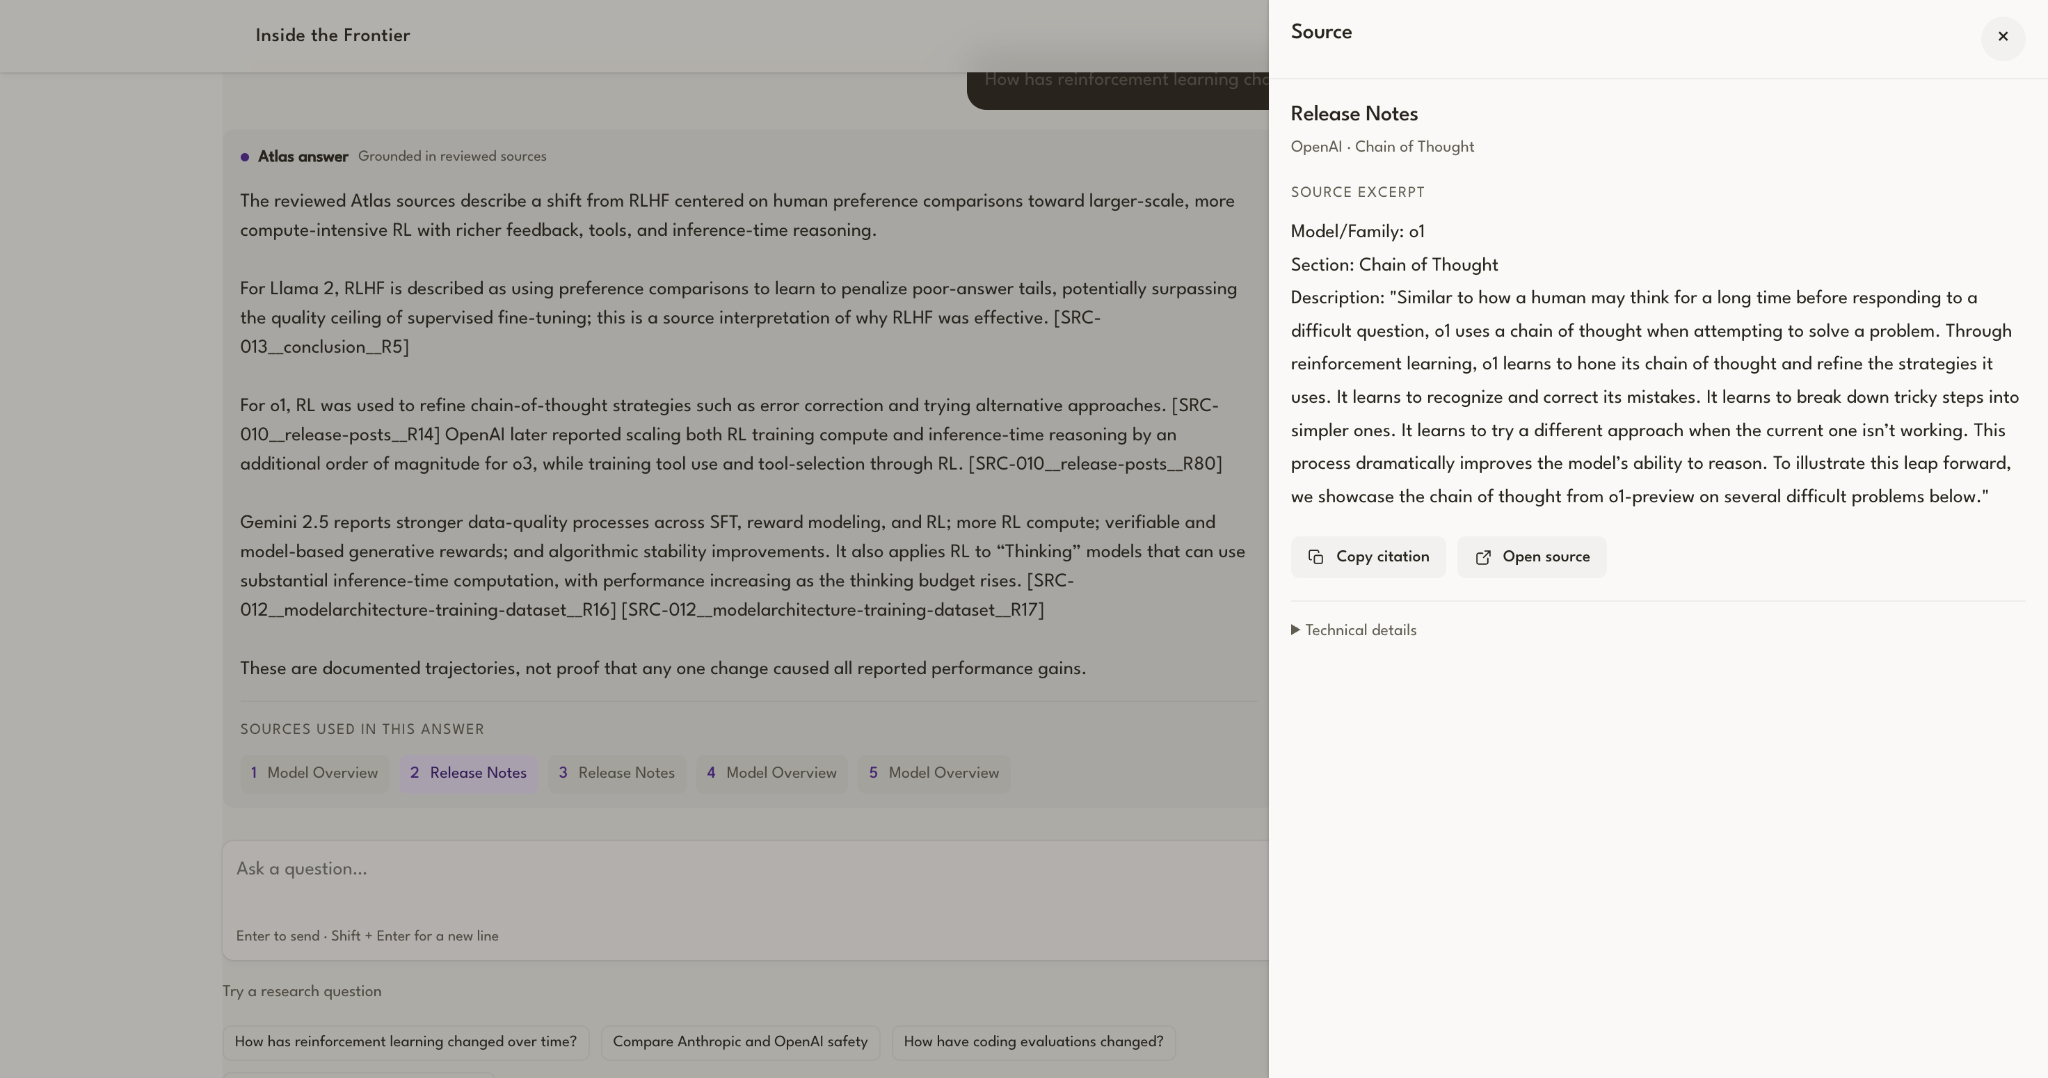
Evidence drawer
Readers can inspect the source excerpt behind a claim.
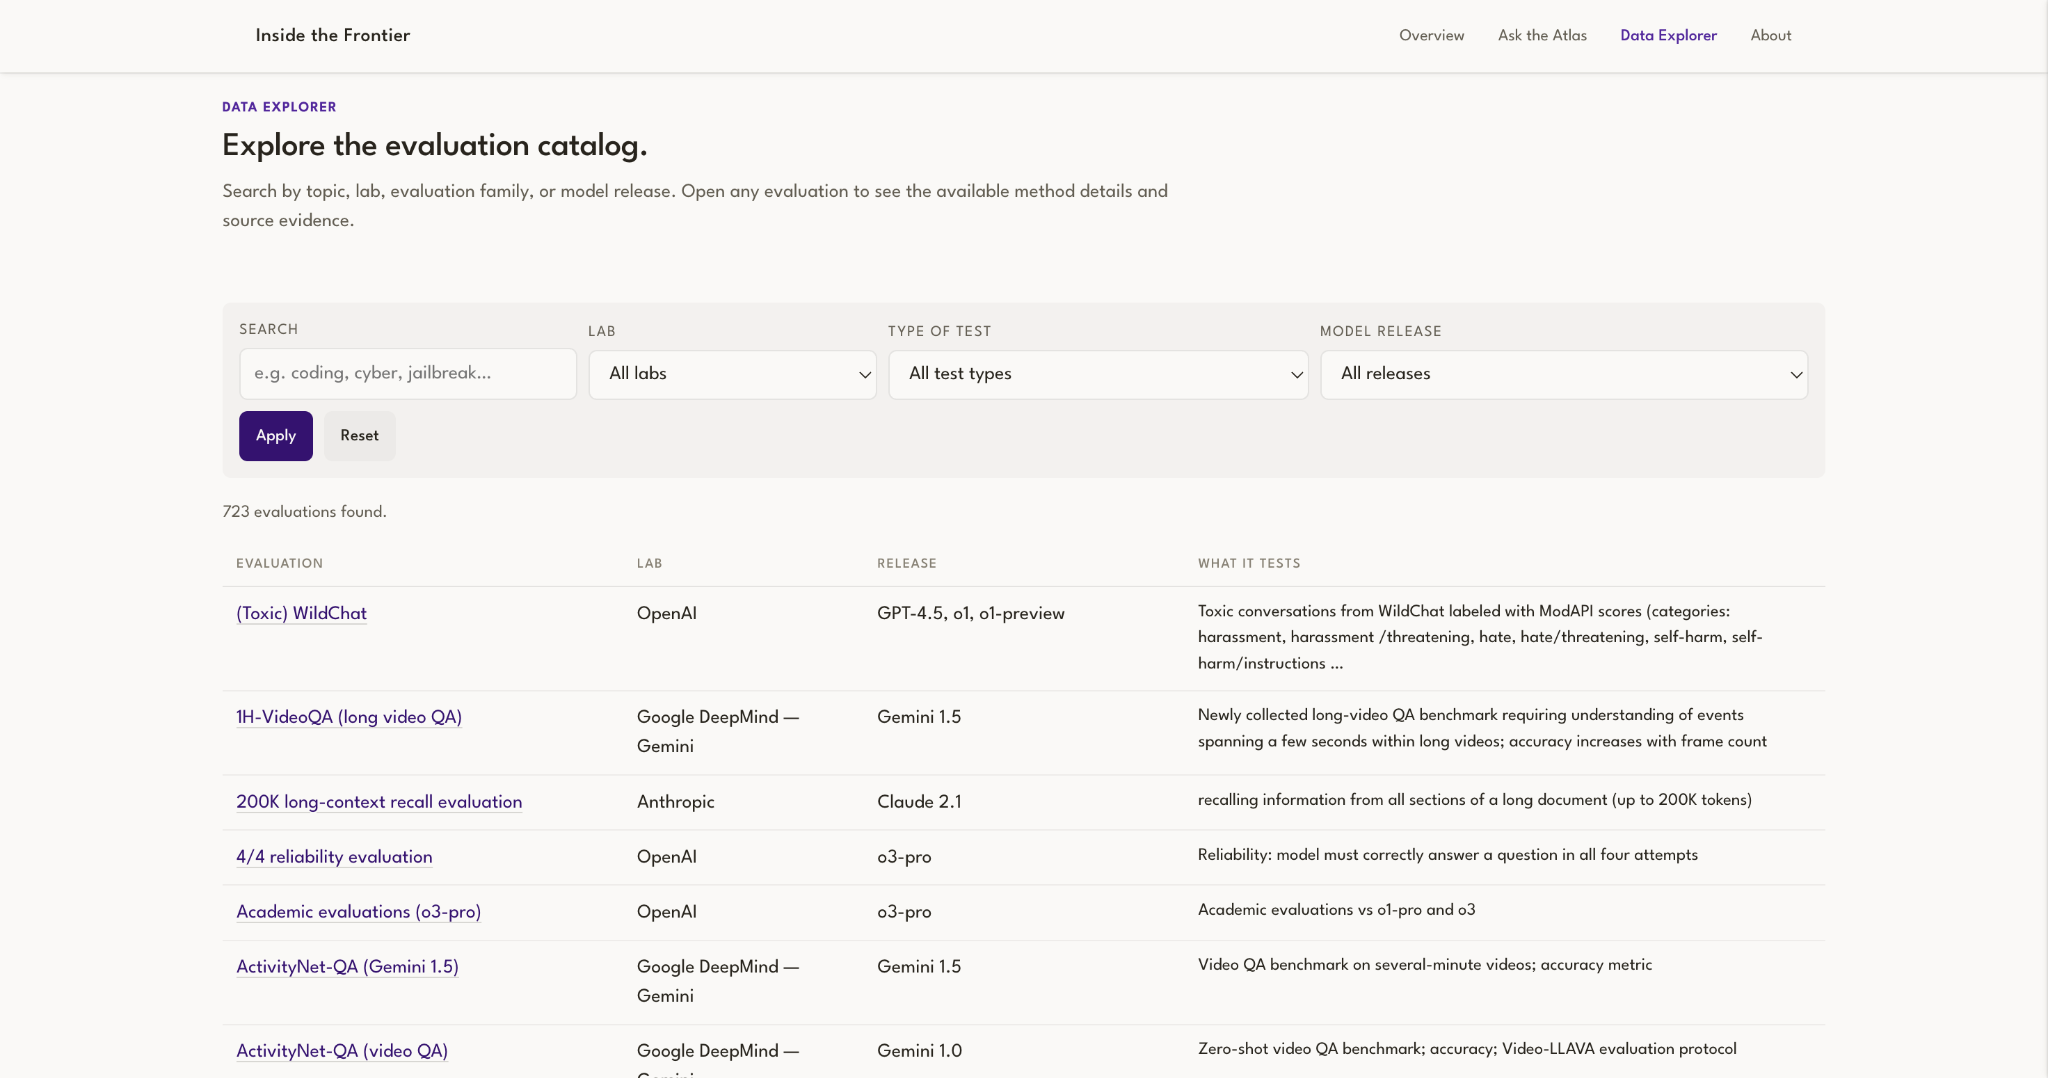
Data explorer
Structured records make evaluation evidence searchable by lab and release.
03 / Method
Design the evidence boundary before the interface.
I kept curation, extraction, comparison and retrieval as separate stages. That made missing evidence visible and stopped fluent synthesis from outrunning the public record.
Research principle
Where the public record stops, the product should say so.
01
Curate
Set the source boundary.
02
Extract
Structure the evidence.
03
Compare
Audit the protocol.
04
Retrieve
Return claims with sources.
Working on a hard product problem?
I’m exploring GTM Strategy, AI Product, Product Strategy, and Forward Deployed roles.